

Under review · 2026
Inverse Reinforcement Learning without an Optimal Demonstrator: A Feasible Reward Set Approach
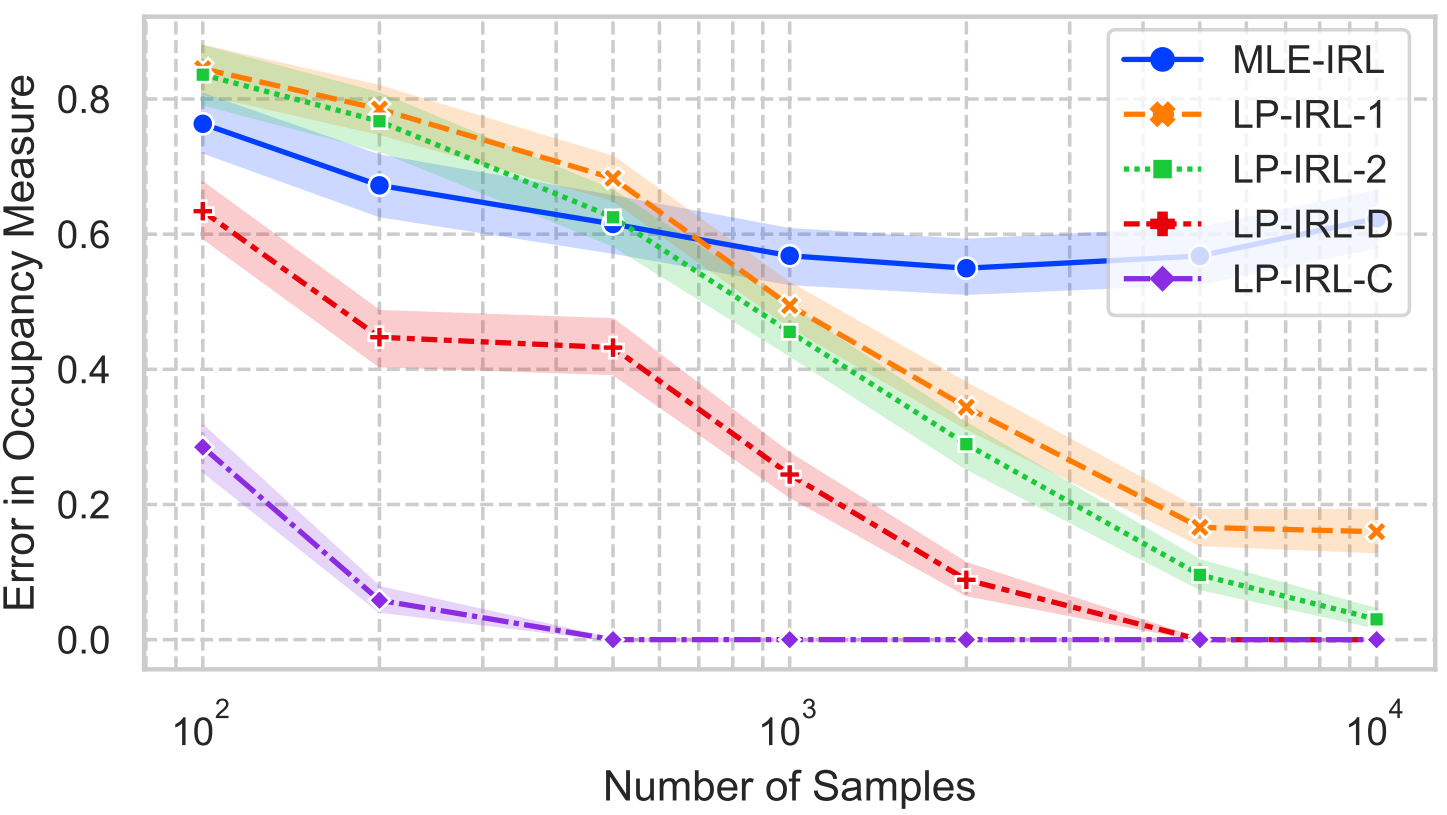
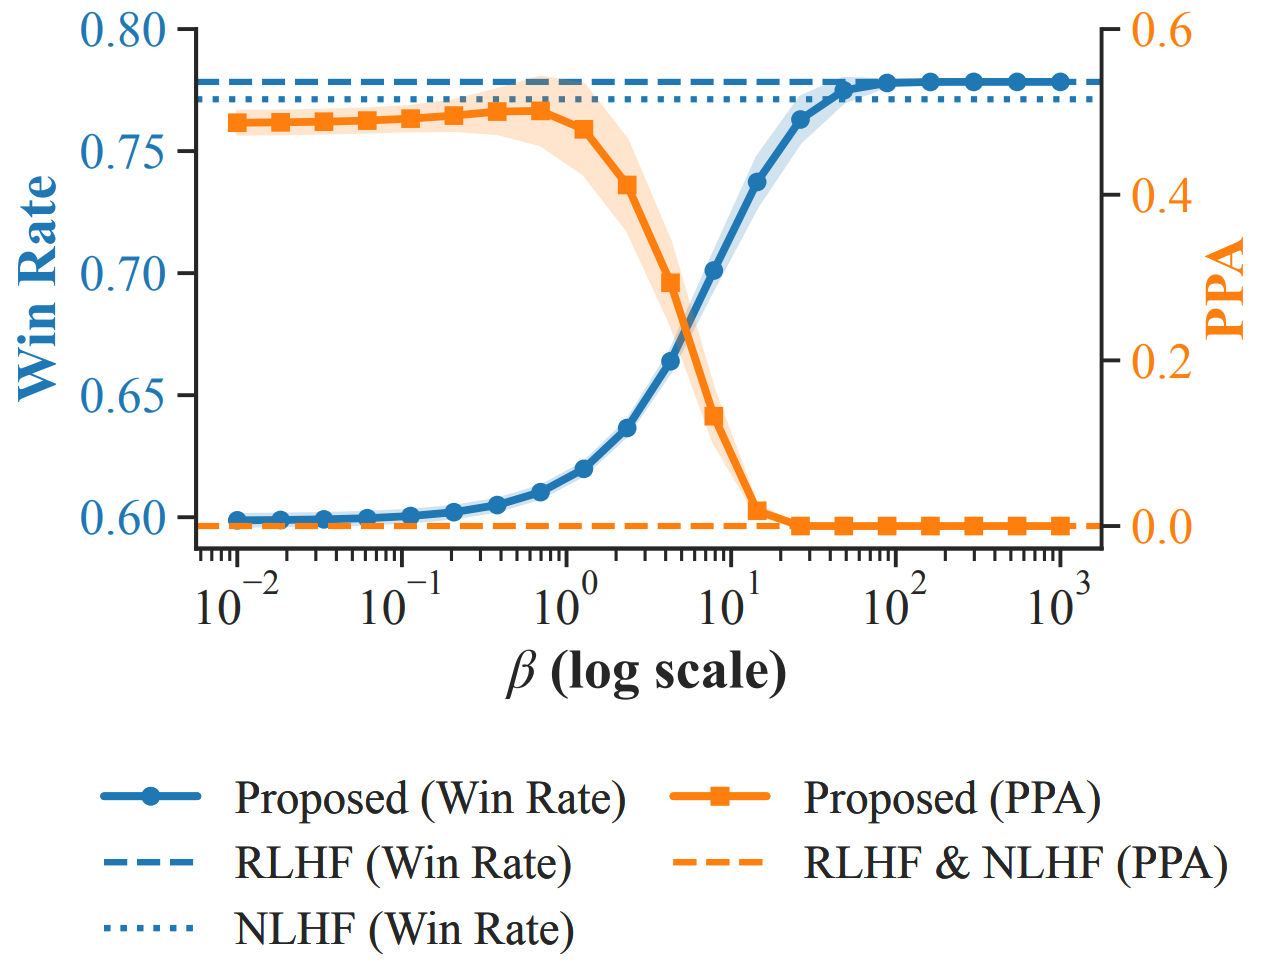
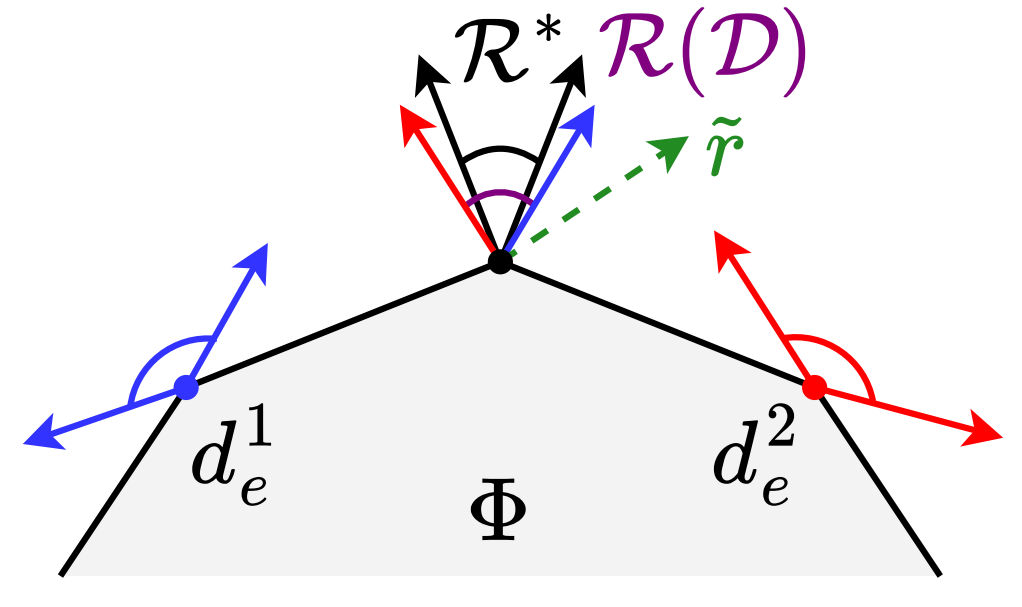
We study how to infer rewards from multiple imperfect demonstrators with different levels of suboptimality. Our framework translates their suboptimality into linear constraints and combines them into a feasible reward set, with guarantees that can hold without a near-optimal demonstrator under sufficient coverage. An offline algorithm extends the approach to function approximation, with experiments in grid worlds and LLM fine-tuning.
Paper